Wesley Dean

DevSecOps Engineer, Author, and Mentor

I’m a technologist, author, and mentor who helps people and organizations move from complexity to clarity. Through consulting, writing, and workshops, I bridge the gap between technical and non-technical teams, translating risk into meaningful decisions and sustainable action. My work centers on leadership, connection, and disciplined execution, drawing on decades of experience to help teams build secure, reliable systems while strengthening trust, alignment, and shared understanding.

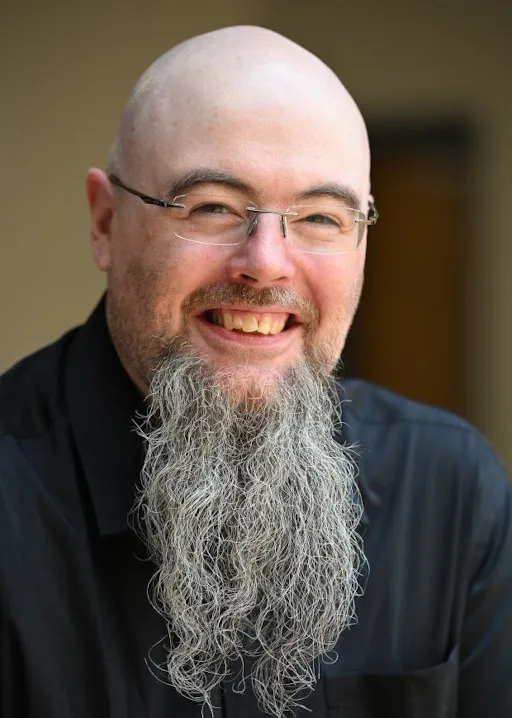
Picture of Wesley Dean wearing a black dress shirt

Latest 3 Posts ↓

View all posts →
awk-doxygen, Doxygen documentation for AWK image

awk-doxygen, Doxygen documentation for AWK

11 min read

A few days ago, I wrote about bash-doxygen, a Doxygen filter I built for documenting Bash functions and variables. There is a mildly amusing detail buried inside that project: the core of the filter is itself an AWK script.

That is hardly unusual.

I have encountered AWK repeatedly over the years in places where Bash alone stopped being the right tool for a particular part of the job. A shell script might orchestrate commands, files, and processes, then reach a point where it needs to parse records, transform structured text, maintain state, or perform more substantial pattern matching. AWK fits that space well.

It is also one of those tools that seems to exist almost everywhere while receiving surprisingly little attention.

That combination creates an interesting maintenance problem.

AWK programs are often compact, capable, and stable enough that somebody writes one, gets it working, and then leaves it alone for a long time. Months or years later, another person opens the file and encounters an execution model that differs from the surrounding shell code, along with variables that spring into existence through use, pattern/action rules that behave unlike ordinary functions, and function parameters that may conventionally serve as local variables.

That is exactly the sort of code for which documentation earns its keep.

So I built awk-doxygen.

Like bash-doxygen, awk-doxygen is a documentation-led Doxygen filter. It takes explicitly documented AWK constructs and translates them into a small Doxygen-friendly pseudo-C++ representation. It does not attempt to turn AWK into C++, and it does not claim to be a complete AWK parser.

The maintained source remains AWK. The generated representation exists only so Doxygen has something it already knows how to index.
Read More

bash-doxygen, Doxygen documentation for Bash image

bash-doxygen, Doxygen documentation for Bash

6 min read

Last week, I wrote about mktext, a small library that came out of a larger Bash project and became useful enough to deserve its own boundary. bash-doxygen is another tool in that family, although it solves a very different problem: turning carefully documented Bash source into something Doxygen can understand.

I have used Doxygen for years because I like keeping implementation-level contracts close to the code they describe. Bash is awkward territory for that approach. Doxygen understands several programming languages directly, but Bash is not one of the languages for which it can reliably infer functions, parameters, variables, and declarations on its own.

One answer would be to build a Bash parser. That would be a much larger project than the problem justified.

Instead, bash-doxygen takes a narrower approach. It looks for Doxygen-style comment blocks immediately followed by recognizable Bash declarations, then emits a small pseudo-C++ representation that Doxygen can index. Undocumented helpers remain undocumented. Source that does not participate in the documentation contract is left alone.

Read More

mktext, a focused text-substitution library image

mktext, a focused text-substitution library

6 min read

While working on adrctl, I found myself needing a small piece of functionality that was useful there but was not inherently about Architecture Decision Records: substitute caller-supplied values into text.

adrctl needed that capability in two closely related places:

  • users should be able to define patterns for ADR filenames;
  • users should be able to substitute values into ADR body templates.

Both cases involve text containing named tokens that need to be replaced with values. That is also how Nat Pryce’s adr-tools handles ADR templates. Since one of adrctl’s goals is compatibility with adr-tools, existing templates using bare tokens such as TITLE, NUMBER, DATE, and STATUS needed to keep working.

I looked at several libraries and template engines. They were capable tools, but most did considerably more than I wanted. I did not need a programming language hidden inside a template. I needed predictable text substitution with a very small semantic surface.

So, mktext was born.

Read More

40 more posts can be found in the archive.